Why are focus groups the hardest audio to transcribe?
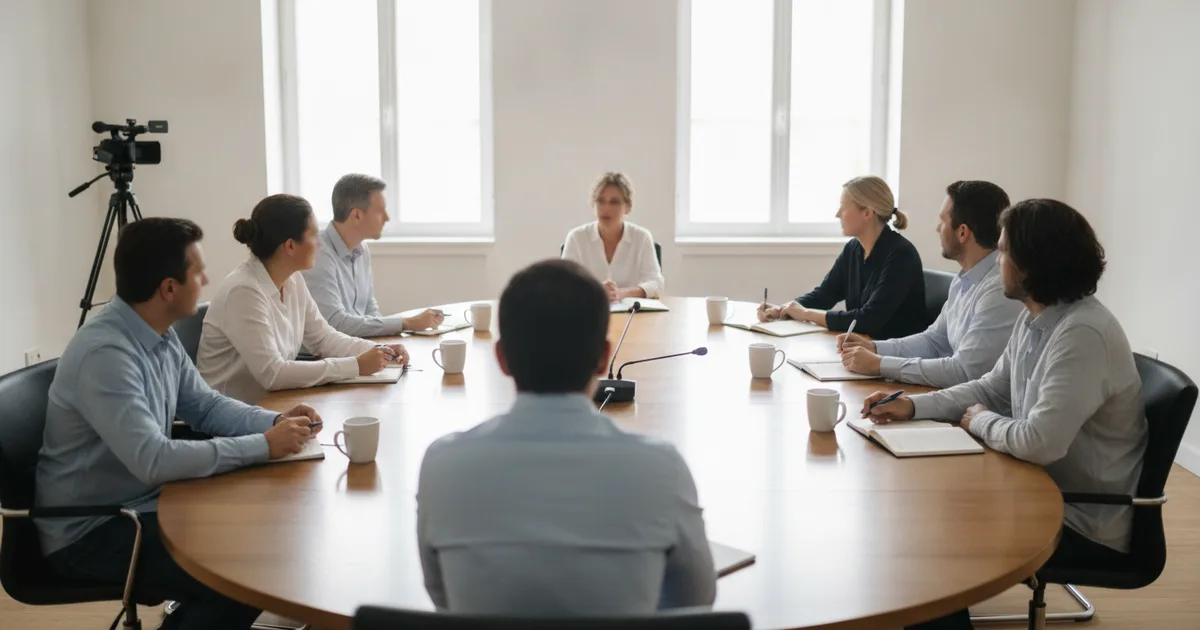
Focus groups are hard to transcribe because several people talk to each other rather than to one interviewer. Voices overlap, short reactions fly across the table, participants sit at different distances from the microphone, and the transcriber has to work out not only what was said but who said it.
The whole point of the method is interaction, so the richest moments are often the messiest on the recording: two participants disagreeing at once, a burst of laughter, someone finishing another person's sentence. Julia Bailey's methods paper on transcribing notes that transcription takes at least 3 hours per hour of talk, and up to 10 hours per hour when a fine level of detail is needed. Group recordings, with their overlapping voices, usually sit towards the slow end.
The difficulties fall into five groups:
- Overlapping speech: people talk over each other when the discussion gets lively
- Similar voices: several adults of the same age and accent are hard to tell apart on audio alone
- Uneven distance to the microphone: the nearest person is loud, the one at the far end faint
- Back-channel talk: "yeah", "exactly" are short and easy to misattribute, yet they can signal agreement you want to analyze
- Moderator versus participants: prompts must be clearly separated from the group's answers
The quality of your transcript is therefore decided long before anyone types a word, when you plan the recording.
How should you record a focus group to make transcription easier?
Record a focus group with a good central microphone, a backup recorder, a seating chart and a round of introductions. These habits cost minutes on the day and save hours of guesswork afterwards.
Microphone placement: one mic or several?
One omnidirectional conference microphone in the middle of the table works for a small group seated close together. For a long table or soft-spoken participants, add a second recorder at the other end, or individual lapel microphones if your setup allows: separate channels make attribution far easier but add a synchronization step. Either way, run a short sound check with the actual group.
For online focus groups on Zoom, Teams or Meet, use the platform's recording or capture your computer's system audio, and ask participants to wear headsets and mute when not speaking. A 2024 methods paper by Eftekhari on speech recognition in qualitative research recommends good quality audio, headsets to minimize echo, less overlapping speech and a quiet environment to limit transcription errors.
Video, seating chart and introductions
- Video as a speaker aid: a camera in the corner helps you see who spoke during a heated exchange. If you film, make sure your consent process covers video and keep it only as long as you need it.
- A seating chart: note each participant's code (P1, P2...) and seat. The note-taker can also jot down the first words of key contributions with a time stamp.
- Introductions on tape: ask each participant to say their code or first name and one short sentence. You get a clean voice sample for every person, invaluable when you match voices to labels.
- Ground rules: a friendly "one person at a time, please" will not eliminate crosstalk, but the moderator can come back to it when the discussion overheats.
Tip: when two people talk at once, a good moderator briefly names the next speaker ("Let's hear from P4 first, then P6"). It keeps the discussion fair and leaves a verbal marker on the recording that makes attribution much easier.
Full verbatim or clean verbatim for a focus group?
Choose clean (intelligent) verbatim if you plan a thematic or content analysis, and full verbatim if the interaction itself is your data. For most applied, market and UX projects clean verbatim is enough; studies of how opinions form in the group, or of how people talk, need full verbatim with overlap marked.
| Your analysis | Recommended style | What to keep in the transcript |
|---|---|---|
| Thematic or content analysis | Clean verbatim | Every contribution and speaker label; fillers and false starts removed |
| Market or UX research findings | Clean verbatim | Quotable statements, clear attribution, time stamps to find clips |
| Analysis of group interaction | Full verbatim | Overlaps, interruptions, laughter, agreement and disagreement markers |
| Conversation or discourse analysis | Full verbatim with notation | Pauses, overlap onsets, emphasis, following a convention such as Jefferson |
Even with clean verbatim, do not strip the short reactions that carry meaning in a group. "Yeah, same" from three participants is evidence of shared experience, and the Eftekhari paper lists square brackets as a common convention for marking overlapping talk or emotion. For the two styles in depth, see our guide to verbatim vs clean verbatim transcription; for transcription across qualitative methods, see our guide to transcription in qualitative research.
How do you label and anonymize speakers?
Label every turn with a stable code, such as M for the moderator and P1 to P8 for participants, and keep the key that links codes to real people in a separate, secured file. Codes are easier to anonymize than names and stay consistent across groups.
- Prefix codes by group when you run several sessions (G1-P3, G2-P3) so participants from different groups never share an identifier.
- Use "Unidentified" rather than guessing. If you cannot tell who spoke, write [P?] or [Several]: a wrong attribution silently distorts any analysis by participant.
- Watch what your labels imply. The Eftekhari paper recommends checking whether a naming convention maintains pseudo-anonymity or ascribes a role, gender, identity or power relation.
- Replace identifiers consistently. The UK Data Service guidance on anonymizing text data advises replacing names, employers and specific locations with pseudonyms or descriptive tags such as [colleague 1], applying replacements consistently across transcripts, and keeping an anonymization log of what you changed.
In a group, participants also name each other ("As Sarah said..."): replace those names with the matching code too.
Sample focus group transcript (clean verbatim, illustrative):
[00:21:08] M: What made you stop using the app after the first week? P3: Honestly, the notifications. It felt like it was nagging me. P5: [overlapping] Same, I turned them off on day two. P3: Right, and then I just forgot it existed. P1: I had the opposite experience, actually. I liked the reminders. [Several]: [laughter] M: Tell me more about that, P1.
What makes it analysis-ready: a time stamp, a distinct moderator label, participant codes instead of names, an overlap marker where P5 cut in, and a group reaction honestly attributed to several people.
How to transcribe a focus group step by step
The fastest reliable workflow is an AI first pass followed by a careful human review: the machine types, you listen and judge.
Plan the recording
Choose your microphones, a backup recorder and, if relevant, a camera. Assign participant codes and prepare the seating chart.
Record with introductions and a seating chart
Confirm consent to recording, run introductions so every voice is heard once on its own, and have the note-taker fill in the seating chart and flag key moments.
Run an AI first pass
Upload the recording to a transcription tool that separates voices. You get a time-stamped draft with generic labels (Speaker 1, Speaker 2...). Treat it as a draft, never as the final transcript.
Map voices to participant codes
Use the introductions, the seating chart and any video to match each generic label to a participant, then rename the labels M, P1, P2 and so on.
Review against the audio, crosstalk first
Listen back while reading, prioritizing overlaps, quiet speakers, jargon and proper nouns. Fix attributions, split merged turns and mark what you cannot resolve as [inaudible] with a time stamp.
Anonymize and add a header
Replace names and identifying details consistently, log the replacements, and add a header (group ID, date, moderator, number of participants, convention).
Export for analysis
Export as .docx or .txt with one speaker label per turn for NVivo, ATLAS.ti or MAXQDA, and keep an unedited master copy.
How long does focus group transcription take, and what does it cost?
By hand, expect several hours of work per hour of recording, and more for a busy group with overlapping voices. With an AI first pass, the typing disappears but the review does not.
What the published figures say
The second figure comes from individual interviews, not focus groups. With more voices and more overlap, plan for a longer review, and time your own first transcript before you budget the rest of the project.
On cost, doing it yourself costs only your time, which the figures above show is considerable. If you request quotes from a human transcription service, check whether the price changes with the number of speakers, the verbatim level, speaker identification and turnaround, since focus groups tend to need all of them. An AI tool plus your own review saves typing time, not thinking time.
Watch out: do not budget focus group review time from a one-to-one interview. Run one group through your full workflow first, measure how long the review really took, then multiply.
What can AI do with crosstalk, and what can't it?
AI handles the clear, one-at-a-time stretches of a focus group quickly and well, but overlapping speech remains its weak spot: expect missing words, merged turns and misattributed speakers where people talk at once.
This is not a limitation of one product. The review of speaker diarization research by Park and colleagues describes speech recognition on overlapping speech as one of the main challenges in meeting transcription, reports that studies of meeting recordings observed an average of 12% to 15% of speaker overlap, and notes that many traditional diarization systems focused only on non-overlapping regions. A lively focus group is rarely an easier case.
In practice, an AI transcription tool will:
- Do well: produce a fast, time-stamped draft of clear speech, separate distinct voices into labeled turns, and save you the hours of typing
- Struggle: keep both sides of a simultaneous exchange, catch quiet back-channel responses, tell apart two participants with very similar voices, and spell specialist jargon or brand names
- Not do at all: know who each person is. Voice separation tells you that Speaker 3 is a different voice from Speaker 5; only you, with your seating chart and introductions, can say that Speaker 3 is P4
The honest rule: AI turns focus group transcription from a typing job into a reviewing job. You still need to listen, especially to the overlapping passages, which often hold the most interesting interaction.
Consent, confidentiality and GDPR for focus group recordings
Recording a focus group needs every participant's informed agreement, a warning that confidentiality within the group cannot be guaranteed and, in the EU and UK, a lawful basis and safeguards for processing the recordings.
The University of Connecticut IRB guidance on focus groups sums up the specifics: disclose the use of recording devices in the consent form and consent discussion, ask each member again at the session whether they agree to be recorded, tell participants that what is said should not be shared outside the group and that the confidentiality of what they say cannot be guaranteed, and ask them not to use names when the session is recorded.
Data protection is a separate question from research ethics. The UK regulator's guidance on the research provisions of the UK GDPR points out that consent to take part in a study is distinct from consent as a lawful basis for processing, and that in most research cases consent is not the most appropriate lawful basis, partly because it can be withdrawn at any time. In a group recording, think in advance about what a withdrawal would mean in practice, and agree the lawful basis with your data protection officer or ethics committee.
Finally, check where your transcription tool processes and stores the audio: a recording of eight voices is personal data about eight people. A processor hosted in Europe that deletes the audio after processing keeps the data trail short for European studies.
How the transcript feeds thematic analysis
A focus group transcript is analyzed at two levels: what was said (themes across the group) and how it was said (agreement, disagreement, how views shifted in discussion). Accurate speaker labels are what make both possible.
For thematic analysis, the approach developed by Virginia Braun and Victoria Clarke is the usual reference point: a family of methods for exploring and interpreting patterned meaning across a dataset. With focus groups:
- Code at the group level first, then check whether a theme is carried by the whole group or by one or two dominant voices.
- Keep speaker codes as attributes in your analysis software so you can filter contributions by participant, group or demographic.
- Code the moderator separately, or exclude their turns, so prompts are not mistaken for participant views.
- Mark consensus and dissent. Short reactions you preserved in the transcript ("same", "no, not for me") are what let you show agreement rather than assert it.
Common focus group transcription mistakes
- Relying on one recorder. A single device with a flat battery or a muffled corner loses a session you cannot rerun.
- Skipping introductions. Without a clean voice sample per participant, matching voices to codes becomes guesswork.
- Publishing the AI draft. An unreviewed draft is fine for your own notes, never for coding or quotes.
- Guessing speakers. Mark uncertain turns as uncertain instead of forcing an attribution.
- Deleting group reactions in the name of clean verbatim, and with them the evidence of consensus.
- Mixing conventions across groups. Write your transcription rules down before the first session and stick to them.
- Forgetting names spoken aloud during anonymization, including names of colleagues, employers and places.
Where AudiosTranscribe fits
AudiosTranscribe provides the AI first pass described above: a time-stamped transcript with voices separated into distinct speakers, ready for your review.
What focus group researchers get:
- Automatic voice separation: turns are split by speaker; you decide who is who and rename labels (M, P1, P2...) in one click
- Upload or record: upload an audio or video file from the web app in any browser, or record an online focus group on Zoom, Teams or Meet with the Windows desktop app, which captures system audio and microphone without a bot joining the call, with participants' consent; transcription runs after the recording
- Exports to TXT, Word, PDF and SRT on paid plans, for NVivo, ATLAS.ti or MAXQDA
- Speaker analytics (talk time, approximate where voices overlap) on the Pro plan, handy for spotting a participant who dominated the discussion
- Hosted in Europe, GDPR compliant, audio deleted after processing
- 120 free minutes per month to test the workflow on a real session; research teams can share a workspace on the Team plan (39 € per month for the workspace, VAT not applicable, up to 20 members, 20 hours of transcription pooled per month)
For one-to-one interviews, see our interview transcription page; the pricing page details each plan.
Sources and further reading
- Bailey, J. (2008). First steps in qualitative data analysis: transcribing. Family Practice, 25(2), 127 to 131.
- Eftekhari, H. (2024). Transcribing in the digital age: qualitative research practice utilizing intelligent speech recognition technology. European Journal of Cardiovascular Nursing, 23(5), 553 to 560.
- Park, T. J., Kanda, N., Dimitriadis, D., Han, K. J., Watanabe, S. and Narayanan, S. A Review of Speaker Diarization: Recent Advances with Deep Learning Computer Speech & Language, 72, 101317 (2022); preprint arXiv:2101.09624.
- UK Data Service. Anonymisation for text data.
- University of Connecticut, Office of the Vice President for Research. IRB researcher guide: focus groups.
- Information Commissioner's Office. The research provisions: principles and grounds for processing.
- Braun, V. and Clarke, V. Thematic analysis (the authors' resource site).
Your institution's ethics committee or IRB may set stricter rules, so check its requirements before your first session.